Cron Jobs
Cron Jobs: The Complete Guide for 2026
If you’ve spent any time working on a *nix-based operating system, chances are you’ve heard the term cron job, but for many developers cron jobs remain a source of confusion and painful mistakes.
In this article, you will learn more about the basics of cron, exploring the syntax for creating a cron job, as well as how to manage your cron jobs using the crontab command. We’ll also review common mistakes that developers make when configuring cron jobs.
What Is a Cron Job?
A Cron Job is a Linux program that allows users to schedule the execution of a piece of software, often in the form of a shell script or a compiled executable. Cron is typically used when you have a task that needs to be run on a fixed schedule, and/or to automate repetitive tasks like downloading files or sending emails.
At its most basic level, a cron job is an entry written into a table called the cron table, otherwise known as the crontab for short. This entry contains a schedule and a command to be executed. The cron daemon (crond) looks for entries in the crontab to determine what jobs it should run, and when it should run them according to the specified schedule.
Note: The examples below are run on the Ubuntu operating system. Different Linux OSs might use different package managers, but all other commands will work the same.
How Do Cron Jobs Work?
Most standard installations of cron consist of two commands:
cronorcrond, which is the daemon that runs the scheduling utilitycrontab, which is the command that allows you to edit the cron entries for your jobs
When you talk about a daemon from a Linux perspective, it’s a program that is running in the background and is noninteractive. This means that the program does not accept any user input and doesn’t display output to the user. The word daemon is historically used in a Unix/Linux context and is not a universal term across different operating systems.
The daemon will be running under the root user. You can run the following command to see if cron is running:
$ ps aux | grep cron
You should see an output like this:
root 617 0.0 0.0 9420 2800 ? Ss 17:00 0:00 /usr/sbin/cron -f
If you received no output from the command at all, either cron isn’t running or is not installed.
On Ubuntu you can quickly install cron by running the following command:
$ sudo apt update && sudo apt install cron
If you’re using something other than Ubuntu, you’ll need to run the equivalent command for your package manager.
Once cron is installed, enable it and start it now. systemctl enable on its own only starts the service at the next boot:
$ sudo systemctl enable --now cron
Cron should now be running, and you should be able to see it if you again run the ps command shown above.
Cron Job Schedule Syntax
A basic crontab entry looks something like this, with the cron job schedule first, followed by the command to run:
*    *    *    *    *   /home/user/bin/somecommand.sh
|    |    |    |    |            |
|    |    |    |    |    Command or Script to execute
|    |    |    |    |
|    |    |    | Day of week(0-6 | Sun-Sat)
|    |    |    |
|    |    |  Month(1-12)
|    |    |
|    |  Day of Month(1-31)
|    |
|   Hour(0-23)
|
Min(0-59)
An asterisk (*) matches all values, so if you take a look at the example above, it specifies that /home/user/bin/somecommand.sh should be run at minutes 0-59 and hours 0-23 on days of the month 1-31 for months 1-12 on days of week 0-6 — or in other words "every minute".
Cron entries can also be configured to run at more complex times. If you want to run four times a day between Monday and Friday, you can use the step operator ( / ) and the range operator ( - ).
0 */6 * * Mon-Fri /home/user/somejob.sh
That entry will run your command every six hours starting at midnight — 12:00 a.m., 6:00 a.m., 12:00 p.m., and 6:00 p.m. — but only from Monday to Friday.
For more scheduling examples, crontab.guru translates an expression into plain English.
Managing Crontab Entries
Once cron is running, it checks for crontab entries in the following files every minute:
- /etc/crontab
- /var/spool/cron/crontabs/$USER on Debian and Ubuntu, or /var/spool/cron/$USER on Red Hat and Fedora (
$USERis the account that owns the crontab, not whoever happens to be logged in)
The first file, /etc/crontab, is a system-generated file containing shortcut commands designed to check for cron table entries in the following directories: /etc/cron.hourly, /etc/cron.daily, /etc/cron.weekly, and /etc/cron.monthly. There are a few other locations where cron jobs can be stored; to learn more about those, you can check out this post. For the purpose of this article, you will concentrate on creating new crontab entries for your user.
You can achieve this by using the crontab command. From the terminal, enter edit mode for your user’s crontab using the following command:
$ crontab -e
The first time you run this command, the OS should ask you what editor you would like to use with a little menu like this:
no crontab for user - using an empty one

Select an editor.  To change later, run 'select-editor'.
  1. /bin/nano    	<---- easiest
  2. /usr/bin/vim.basic
  3. /usr/bin/vim.tiny
  4. /bin/ed

Choose 1-4 [1]:
Select the editor of your choice. If you’ve never used an editor on a Linux system before, go ahead and stick with the suggestion of using nano, as it’s an easy-to-use editor for the most part.
Once you’ve made your selection, the editor you’ve chosen will come up with the default crontab for your user, like this:

Currently, the file is empty, but you are now free to add a cron job entry to the bottom of the file.
Common Cron Job Errors
Up until now, you may have the impression that cron seems like quite a powerful tool and nothing can go wrong while using it. Right? Wrong.
Any experienced system administrator who has spent any amount of time setting up cron jobs will tell you that cron jobs will and do fail all the time, for a myriad of reasons.
Here’s an overview of some of the problems you could run into when setting up your cron jobs.
Scheduling Errors
It’s not difficult to make a mistake with the cron syntax, especially if you haven’t worked with it before. Maybe you’ve swapped around the minutes and the hours part of the syntax. Again, you can always use the crontab.guru website to verify that your syntax is correct.
Environment Variables
Another frequent occurrence is that your shell script works from the command line but not from the cron entry. Cron does not load .bashrc or .bash_profile, so a variable you set there, including $USER, is not defined when the daemon runs the job. Hard-code the value, or load the file yourself from the crontab line. The crontab environment variables guide covers PATH, MAILTO, SHELL, and the variables cron sets on its own. A job that CronitorCLI wraps is still started by cron, so it inherits that same environment.
Script Executable Permissions
By default, when you create a shell script, it does not have execute permissions:
$ touch shell_script.sh
$ ls -als *sh
Output:
0 -rw-rw-r-- 1 user users 0 May 21 13:26 shell_script.sh
The file is missing execute permissions. Give the file executable rights by running the following command:
$ chmod +x shell_script.sh
$ ls -als *sh
Now the output looks like this:
0 -rwxrwxr-x 1 user users 0 May 21 13:26 shell_script.sh
This should fix the missing execute permission that cron needs to be able to run the script.
Disk Space
Your script can be incredibly resilient, yet when system resources are depleted, no amount of resilience is going to help your cron job run successfully. Unfortunately, the only way to prevent this is to stay on top of monitoring your servers for metrics like available disk space, available memory, and sufficient open files.
Job Overlap
You might have a cron entry that runs quite frequently and successfully within seconds. For argument’s sake, maybe you’re running that script every minute. It’s highly possible that an outside variable can interfere with the job completing on time, causing the job to take more than a minute to complete. The cron daemon will happily spawn more copies of your script until you have a small army of them all running at the same time, thus depleting system resources. You’ll need to build in checks like flock to make sure only a single copy of your script is running at any given time.
External Variables
Finally, external variables are beyond your control. If, for example, you have a script that pulls information from a REST API endpoint and something about the endpoint that you’re querying changes without notifying you, your cron job could be failing without your knowledge.
Monitoring Cron Jobs
After you’ve read about the multiple ways your cron jobs can fail, you’re probably wondering about the best way to keep an eye on them going forward.
Let’s take a look at a few helpful options you have to best monitor your cron jobs.
System Logs
Cron does have some system-level logging automatically in place.
On Debian and Ubuntu systems, in /var/log/syslog, the cron daemon reports when it gets started or restarted. On Redhat-based systems, the cron daemon writes log entries to /var/log/cron with the same kind of information.
The daemon also reports when it ran your jobs with log entries like this:
Mar 29 16:00:01 mywebserver CRON[12624]: (user) CMD (/home/user/bin/check-visitors.sh)
Unfortunately, cron does not report on the successes or failures of your scripts. It can’t even tell you if a job didn’t run in the first place.
Custom Metrics
You could write all of the measurement logic into the script that is running from the cron entry directly. That would entail logging events to your own log files or capturing the exit status of your script somewhere separately to be monitored by another process. You could also write any error messages that go to stderr to another error-logging file. This does add extra complexity to your script, though, because you would need to account for as many failure cases as possible.
External Monitoring
Thankfully, there is an easier option. Yes, you could go through all the trouble of making sure each of your scripts can notify you when something goes wrong, or you could capture all script output to special log files.
However, you could also take a look at Cronitor. Cronitor is a monitoring tool for your cron jobs, worker processes, and other services.
You can use their CronitorCLI software to automatically register all your cron jobs and make them visible and configurable from a single monitoring location on their website.
Here’s how you can get started.
1. Grab Your API Key
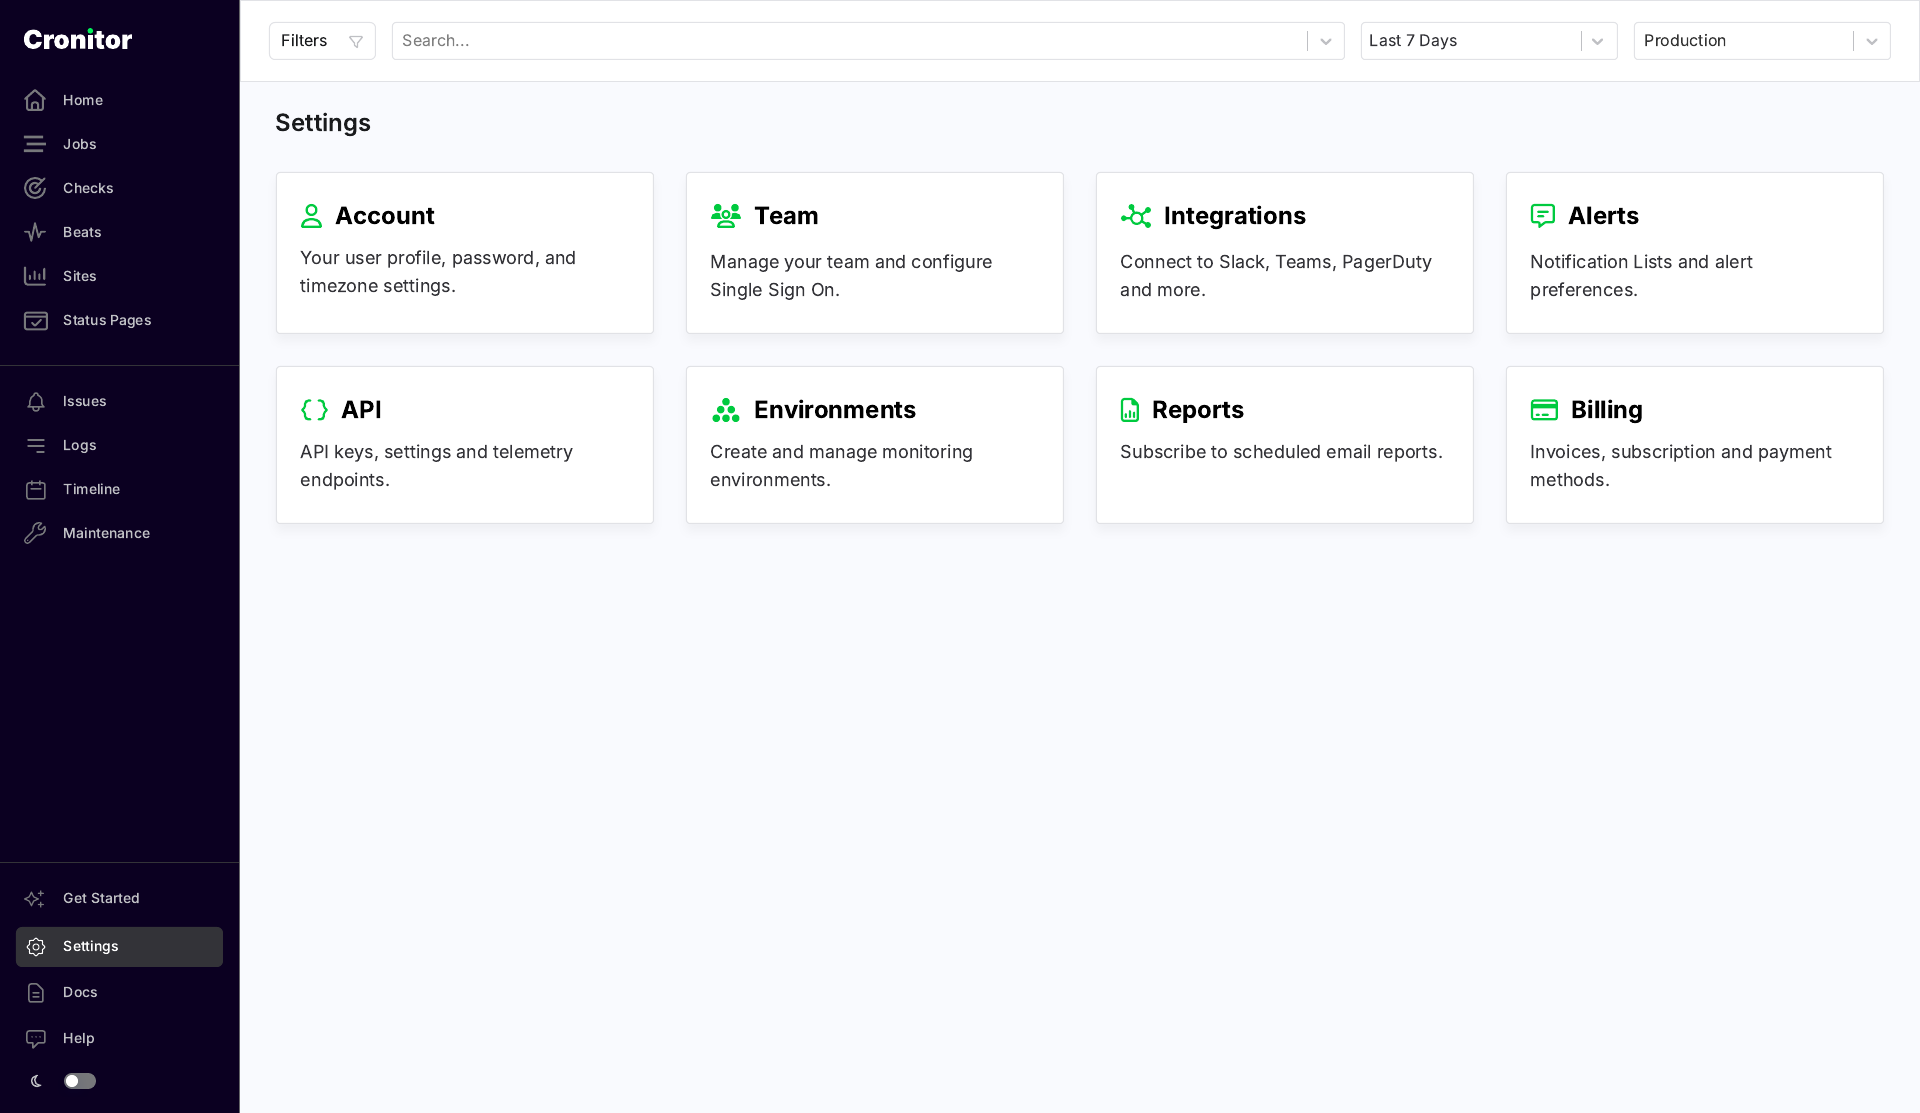
Before you install CronitorCLI, copy an API key. Open Settings, then the API card.
On the API keys page, create a key or copy one you already have. Use an SDK Integration key. That key can create monitors and send telemetry. A Telemetry key can only send events, so cronitor sync cannot create monitors with it. Do not paste the key into a ticket, a log, or a screenshot.
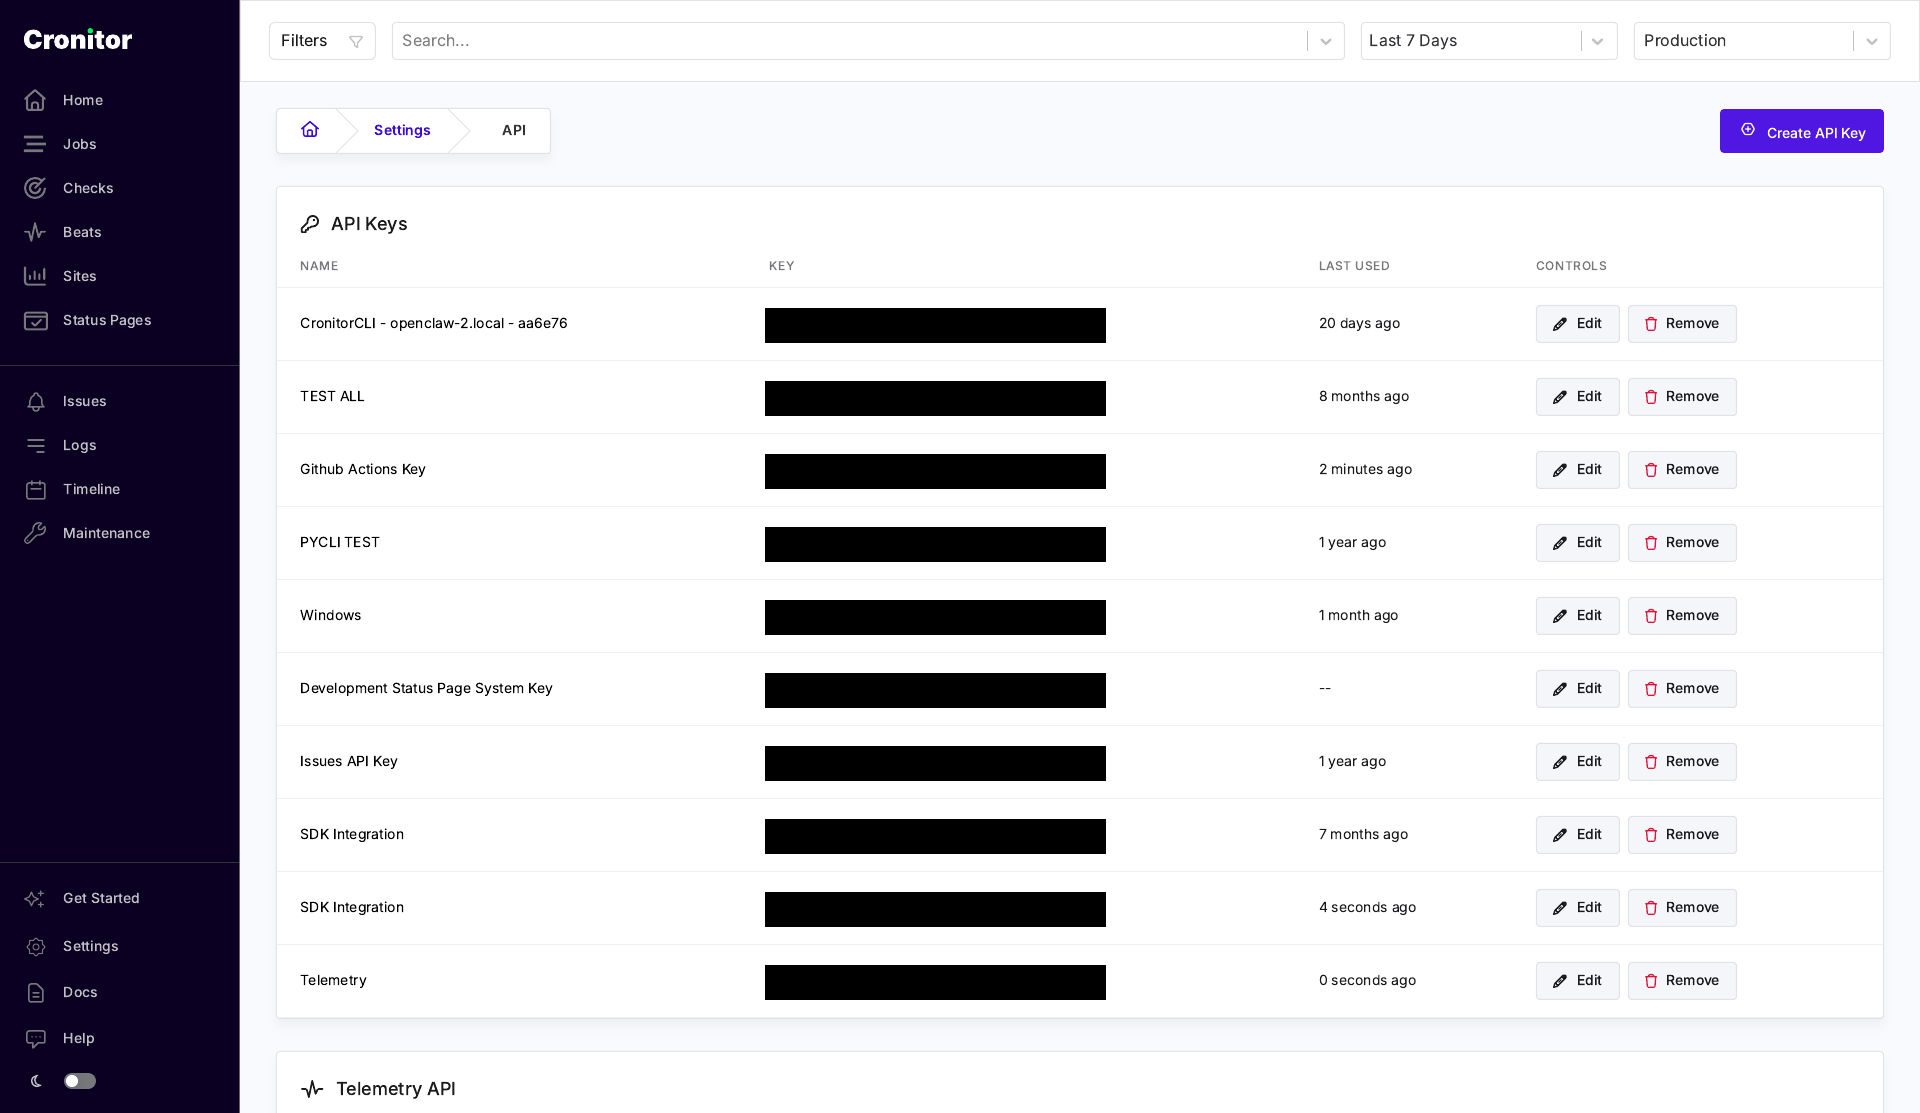
Now you’re ready to install CronitorCLI on your laptop or server.
2. Install the CronitorCLI
It’s recommended that you install CronitorCLI into the system-wide binary directory in /usr/bin. This will allow you to run the cronitor commands without specifying the full path. You can install the binary in another location, but you would need to specify the full path every time you run the command.
The default configuration file is /etc/cronitor/cronitor.json, so you will need sudo to create it.
Copy the commands below to install CronitorCLI. Set CRONITOR_API_KEY to the SDK Integration key in your shell first. The sample below does not show the value.
$ curl -sOL https://cronitor.io/dl/linux_amd64.tar.gz
$ sudo tar xvf linux_amd64.tar.gz -C /usr/bin/
$ export CRONITOR_API_KEY
$ sudo --preserve-env=CRONITOR_API_KEY cronitor configure
If the installation instructions above do not work, it’s possible that the installation procedure has changed since this article was written. If that’s the case, consult the CronitorCLI installation instructions.
The commands above accomplish the following:
- The
curlcommand downloads the latest binary (compressed using gzip) from Cronitor’s website. - The
tarcommand (withsudo) extracts the binary and copies it into/usr/bin. cronitor configurewrites the key to/etc/cronitor/cronitor.json.
sudo drops your environment unless you pass --preserve-env=CRONITOR_API_KEY. The --api-key flag still works, but the key is then stored in your shell history. Prefer the environment variable.
You should see an output that looks something like this. configure prints Set or Not Set. It does not print the key.
Configuration File:
/etc/cronitor/cronitor.json

API Key:
Set

Ping API Key:
Not Set

Environment:
Not Set

Hostname:
linuxguy.invalid

Timezone Location:
{Africa/Johannesburg}
Your hostname and timezone will differ. The new file is owner-only (mode 0600), so other users on the host cannot read it. A job that runs as another account needs CRONITOR_API_KEY in that crontab, or its own config file. See how to run a cron job as a different user.
3. Choose Jobs with cronitor sync
Look at the jobs before you sync them. cronitor sync creates a monitor for each job you accept, and it rewrites that crontab line so cron runs the command through cronitor exec.
$ sudo cronitor sync
Sync walks every crontab it can write. For each job it shows the schedule and the command, then asks you to pick one of three options:
- Monitor this job, using a name based on the command
- Monitor this job and type a different name
- Skip this job
Ctrl+C skips the job on screen and continues. Ctrl+D stops the scan and does not send the jobs from the crontab you were in.
cronitor sync --dry-run still creates the monitors you accept. It does not write the crontab. /etc/crontab and /etc/cron.d are skipped when the command cannot write them, which usually means you need sudo. Your own user crontab does not need sudo.
In this example the crontab pulls a cat fact once a day and writes it to a file:
0 0 * * * /home/linuxguy/scripts/random_catfacts.sh
When sync asks for a name, something short like “Cat Facts” is enough.
cronitor discover is another name for the same command. Prefer cronitor sync. If the schedule later changes, run cronitor sync again so the monitor’s schedule stays in step with the crontab.
4. Read the Job on Cronitor
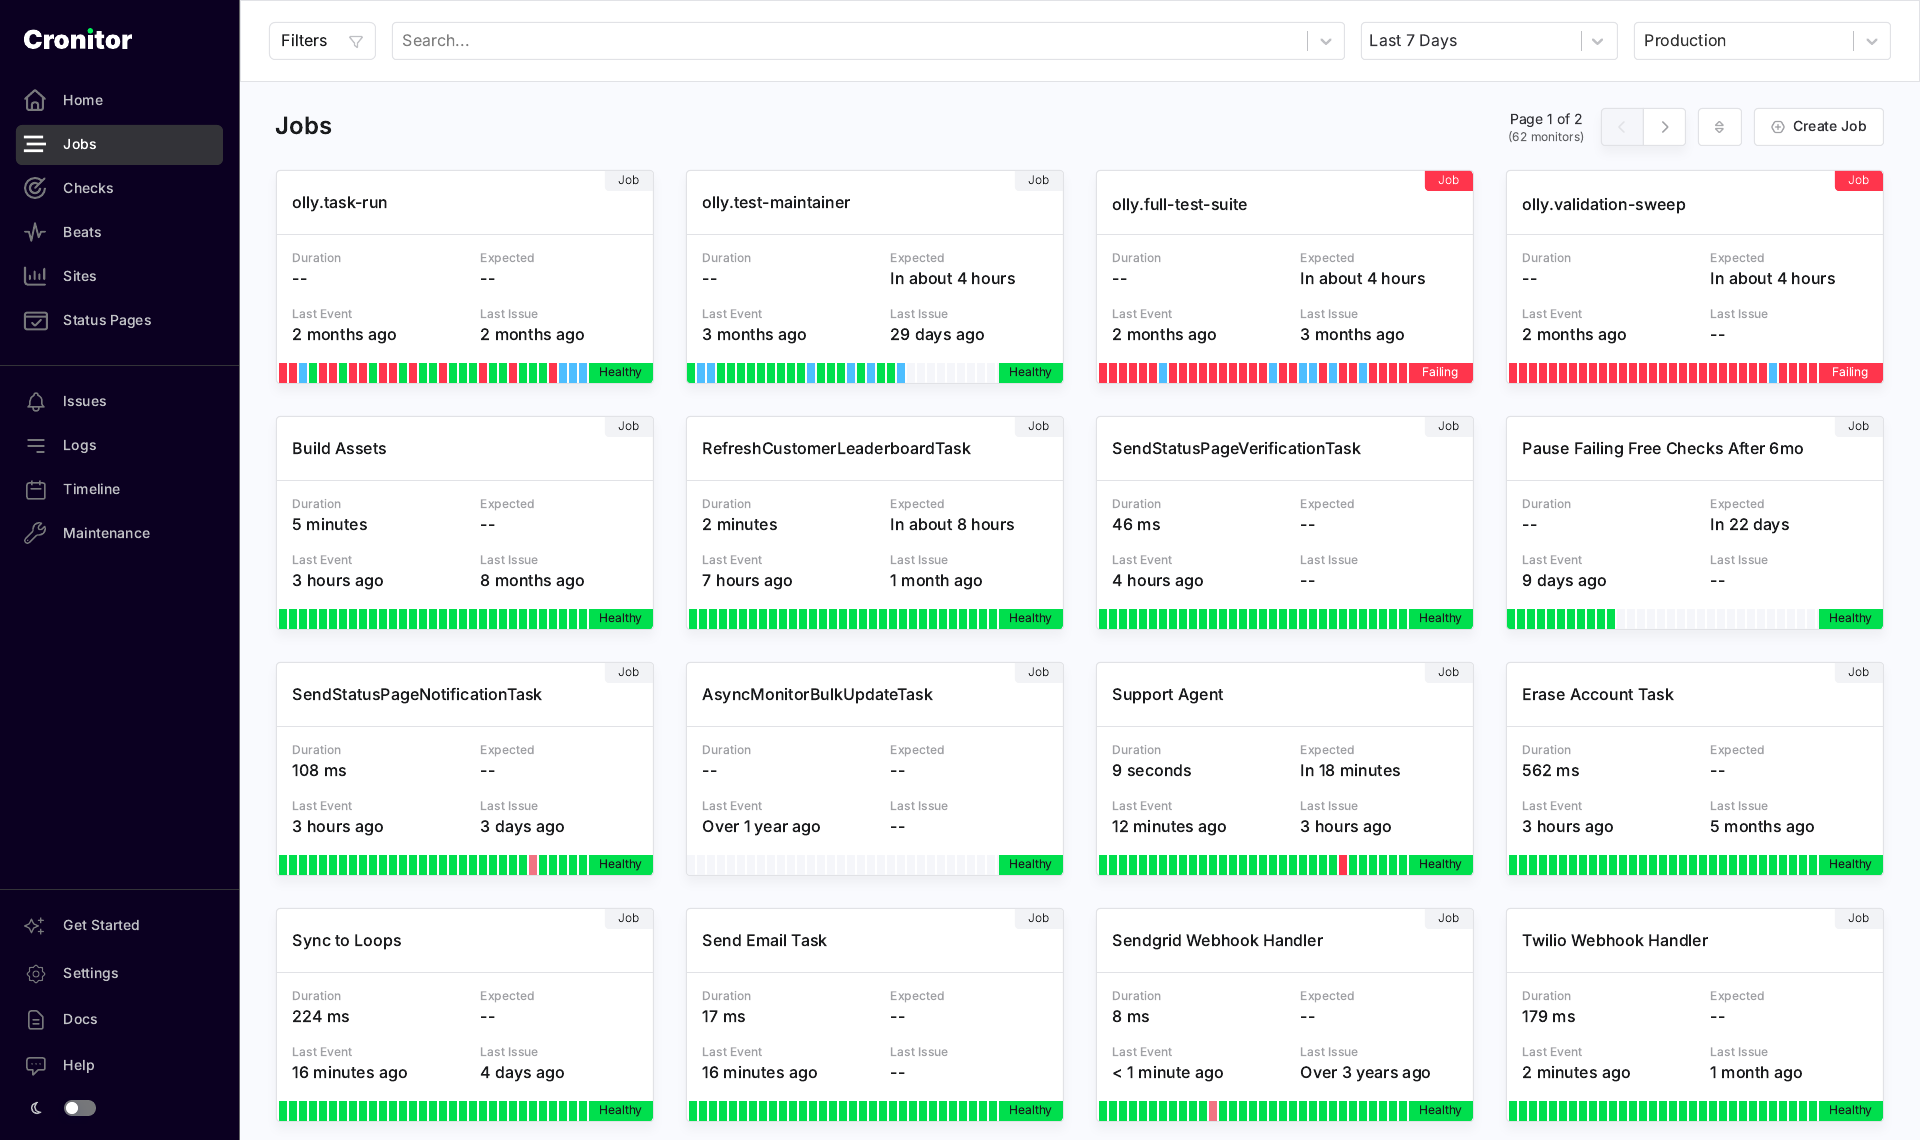
Open the Jobs page. The first time, Cronitor flashes “Nice work! You created your first monitor!” Each card shows Duration, Expected, Last Event, and Last Issue.
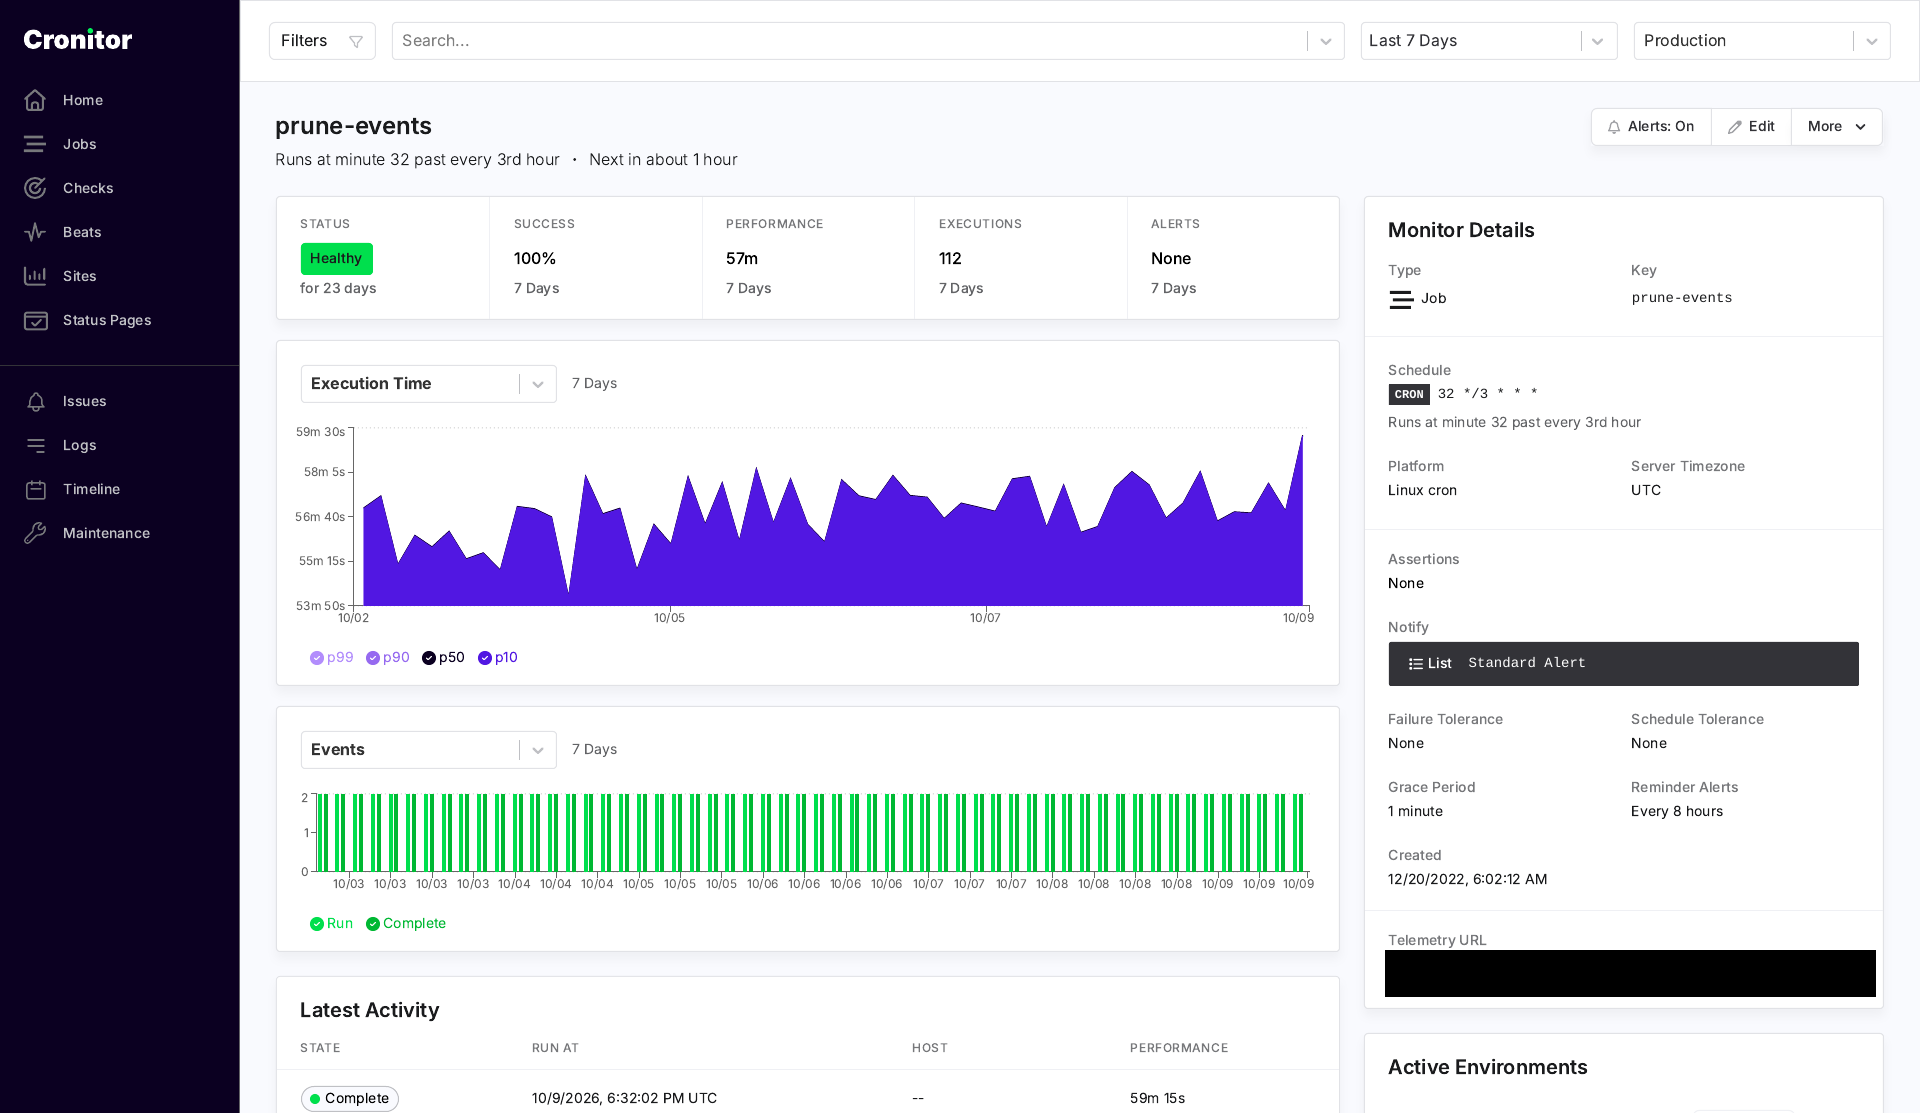
Open the job for the run history. The page shows Status, Success, Performance, Executions, and Alerts, an Execution Time chart, an Events chart, and Latest Activity.
Click Edit. Under The Basics, set the name. Job Details is the schedule, platform, server timezone, and Metric Assertions. Set min duration and Set max duration start unchecked.
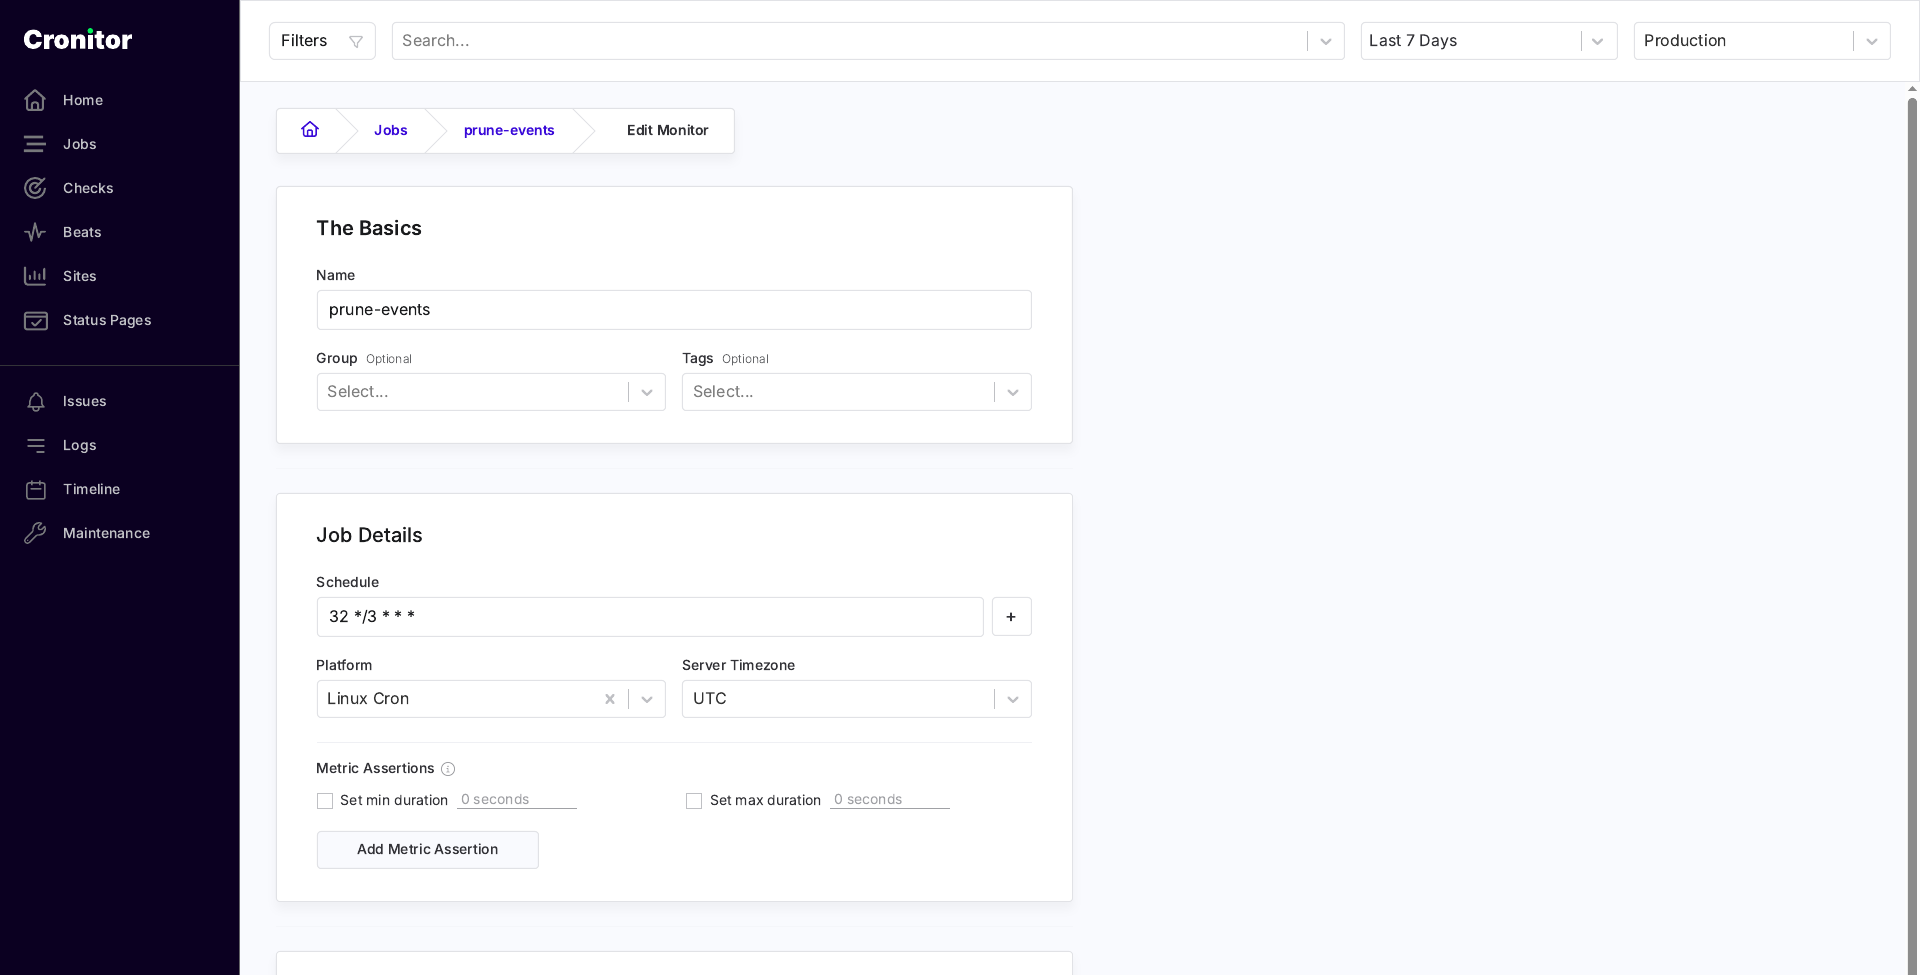
The screenshot leaves both duration checks off. For the cat facts script, turn on Set max duration and use thirty seconds. This is a simple script that pulls a fact from a website, so if it runs longer than thirty seconds, you’d want to know about it.
Alert Settings is further down the same form: Notify, Note, Reminders, Callbacks, Grace Period, Alert Surge Protection, Tolerance, and Auto-Open Incidents.
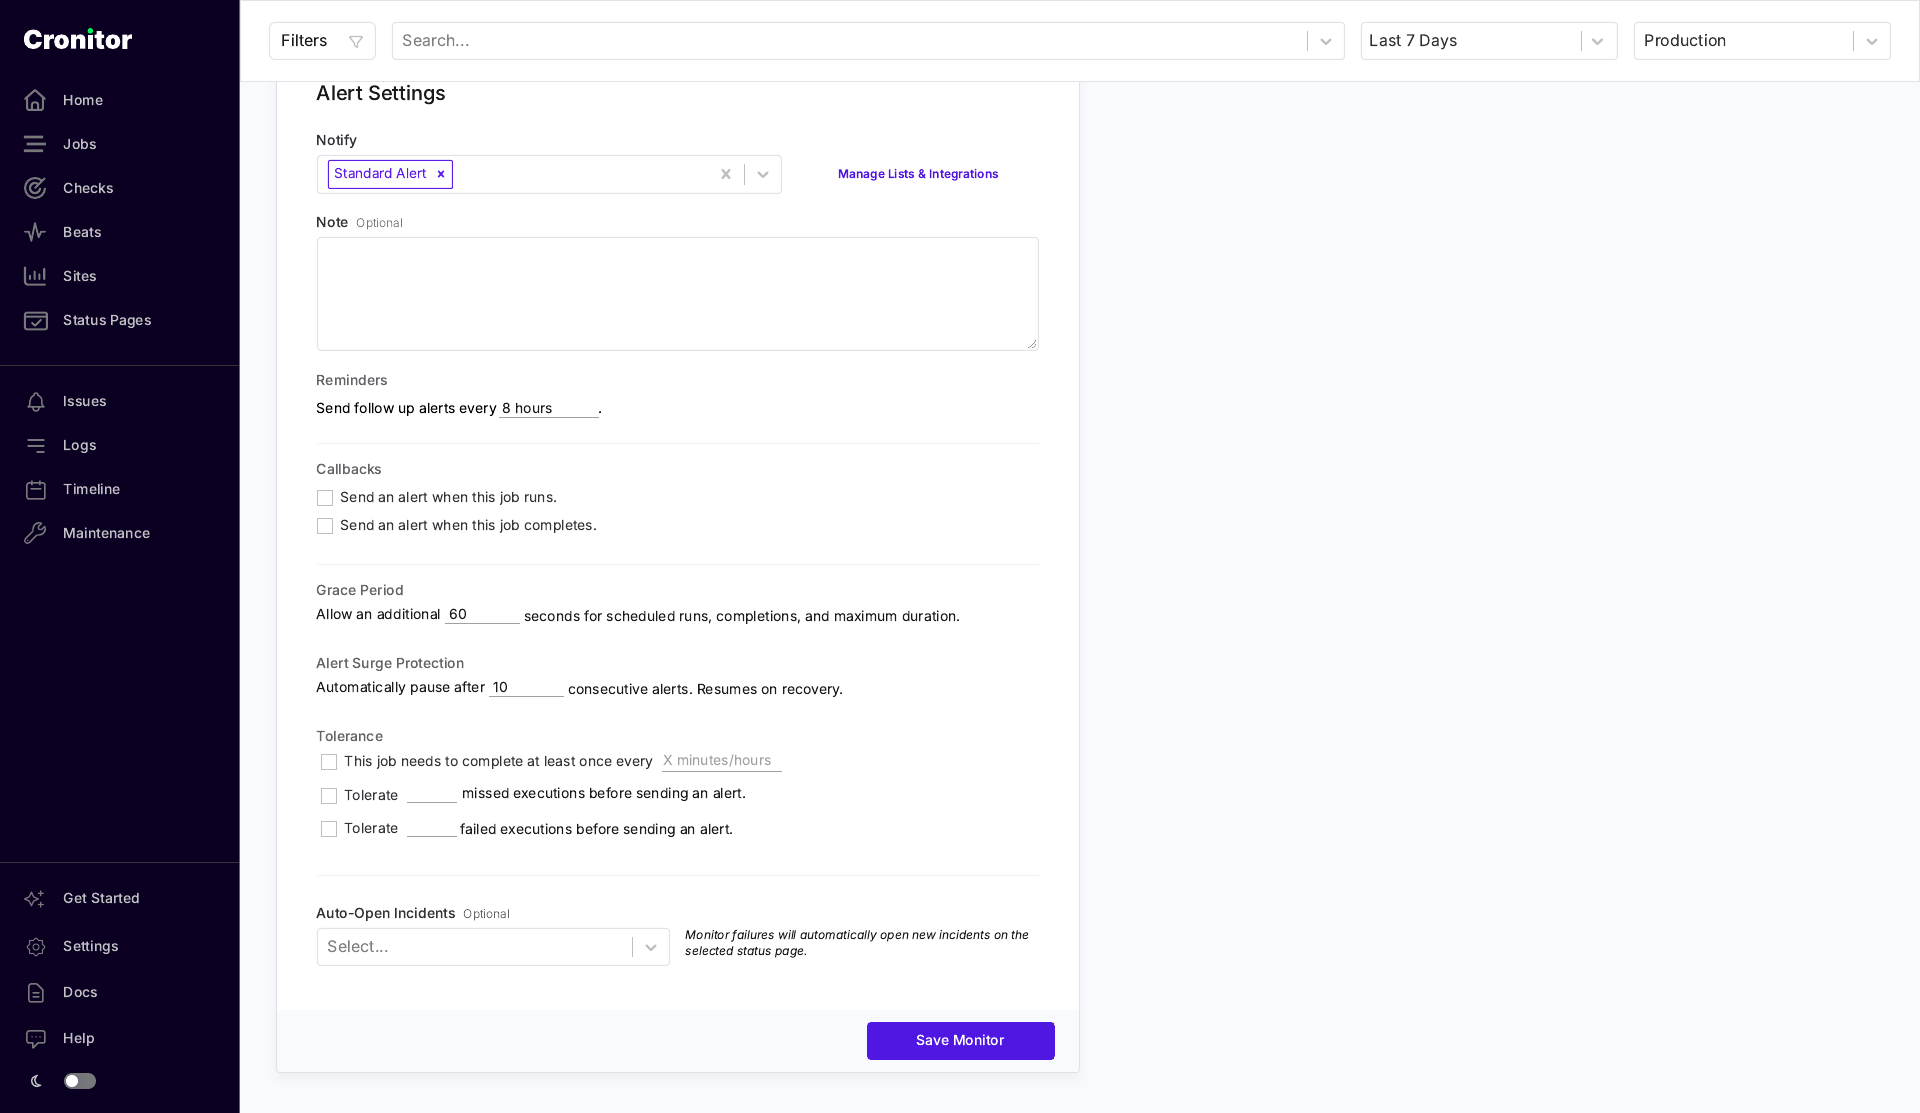
This isn’t a mission-critical job (random cat facts, remember?), so you might only care if you haven’t received a new cat fact after five missed executions. That number is Tolerance for missed executions. Grace Period is extra seconds for a scheduled run, a completion, and maximum duration.
If the script has failed after two executions, something is wrong, possibly because something beyond your control has changed. Maybe the operator of the website now expects you to pay a subscription fee to continue receiving your beloved cat facts, or they closed the site because they now prefer dogs. Failure Tolerance is the setting for that: how many failed executions to allow before an alert.
Job monitoring documents schedules, grace periods, and alerts. Using CronitorCLI is the command reference.
FAQ
Does cronitor discover still work?
Yes. It is an alias of cronitor sync and runs the same command. Top-level cronitor help lists sync. These docs use that name.
Where does CronitorCLI keep its config?
On Linux and macOS the default file is /etc/cronitor/cronitor.json. cronitor configure creates it owner-only (mode 0600). A per-user file is fine too: set CRONITOR_CONFIG to a path that user can write, then run configure without sudo.
Cron Reference
There are a few other ways that your jobs could fail, or cause confusion. We've put together answers to some of the most common questions below.
Where are cron jobs saved?
Learn about the five locations cron jobs can be saved.
Where are cron logs stored?
Learn where cron logs are stored on your operating system.
No MTA installed, discarding output
Learn what causes this message to commonly appear in your syslog.
How to configure cron job env vars
Learn about the various cron config variables.
What is the cron job working directory?
Learn how to list the working directory that cron uses when invoking your job.
How to fix bad minute crontab error
Learn about this common cron configuration error.
How to fix crontab missing newline before EOF
Learn about this common cron configuration error
Fix 'Errors in crontab file, can't install'
Learn what causes this output when saving a crontab file.
How to fix a broken cron job
Learn how to debug common cron job failures.
How to check if a cron job is running
Learn how to check if a cron job is running.
How to view all running cron jobs
View all cron jobs that are currently running.
How to prevent duplicate cron jobs from running
Learn why duplicate jobs are running and what to do about it.
How to run a cron job as a different user
Learn how to schedule a cron job to run as a different user.
How to save cron job output to a file
Learn how to redirect cron job output to a log file
How to run a cron job manually
Learn how to run a command like cron does for testing and validation
Running a cron job in a docker container
Discover two different ways to run cron jobs inside your docker container
Running a cron job every 30 seconds
Learn a simple way to run a cron job every 30 seconds