Monitoring Kubernetes Cron Jobs
Have you ever missed the failure of your Kubernetes CronJobs? Without proper monitoring, it’s easy for things to go unnoticed. Kubernetes CronJobs are an excellent solution for repetitive tasks, but like everything else automated, they do fail at times.
Luckily, developers from Cronitor have created a Kubernetes agent that automatically monitors your CronJobs and can immediately alert you of any interruptions.
This article covers why those CronJobs fail, and how to report the failures with the Cronitor Kubernetes agent.
Kubernetes CronJob Basics
Kubernetes CronJobs run recurring tasks such as backups and report generation. The schedule is the same cron syntax you would put in a crontab.
Monitoring these repetitive tasks — especially those that occur daily or even more frequently — is not a painless duty, especially at scale. Distributed systems like Kubernetes can also add some complexity not seen with Linux cron jobs. Let’s take a closer look at how all this works.

As the diagram above shows, the developer creates and uploads the CronJob into Kubernetes. Then, every ten seconds, the cronjob-controller checks if it is the suitable time to execute the task. When the time is right, the cronjob-controller creates a Job, which schedules the creation of a Pod. The Pod contains one or more containers in which your task is executed. The complex architecture of CronJobs in Kubernetes creates even more space for failures.
Why Do Kubernetes CronJobs Fail?
There are several reasons that your CronJob in Kubernetes might fail. Let’s take a look at what some of the most common failures are due to.
Improper Configurations
To create a CronJob in Kubernetes, you have to prepare a manifest that specifies two main parts:
- When (or how often) execution needs to happen
- What to do upon execution
The manifest is a CronJob configuration, which is typically specified in YAML. You can simply mismatch a single space in YAML, and your code will stop working. Thankfully, in this case, Kubernetes can quickly catch errors during the deployment and inform you of the issue:
$ kubectl apply -f cronjob.yaml
error: error validating "cronjob.yaml": error validating spec: couldn't find jobTemplate
While this scenario isn’t technically a job failure (thanks to improper configuration, you may never see your CronJob execute because it was never created in the first place), it’s a common issue to be aware of.
No More Retries and Concurrency Policies
When your cron job fails for the first time, there could be many reasons for it—the network might be overloaded, or a third-party service may be unavailable. In Kubernetes, you can set up a backoffLimit, which specifies how many retries are allowed to complete your task correctly.
However, this backoffLimit option is tricky, as the retries could impact the next spot for your cron task if set up together with concurrencyPolicy: Forbid. In this case, if the time is right for a new job run but the previous one has not been finished yet, then Kubernetes will skip the new job.
Missing Resources
You can schedule your CronJob to run on specific devices (e.g., on a node with GPU) with more resources (e.g., RAM or CPU) or attached volumes. However, sometimes Kubernetes cannot fulfill the requirement under certain situations. For example, if a node with GPU is missing or doesn’t have enough capacity to run another Pod, your cron task will not even start.
Missing an Execution Spot
Since the Kubernetes cronjob-controller checks your CronJobs every ten seconds, it’s possible that in specific situations, the check could occur less frequently. In that scenario, a particular CronJob would miss the time for execution. Therefore, Kubernetes developers implemented an option called startingDeadlineSeconds to specify how much time can pass in which the cronjob-controller can still schedule the job correctly.
Important Note: If startingDeadlineSeconds is set to anything lower than ten seconds, the cronjob-controller might not schedule every execution, as it only checks every ten seconds.
Monitor Kubernetes CronJobs
Now that you have an understanding of how cron jobs work in Kubernetes and what types of failures are most common, let’s take a look at a couple of strategies for monitoring CronJobs.
First, the Kubernetes community has created a service called kube-state-metrics, which communicates with the Kubernetes API server and exposes metrics about the state of the cluster. Specifically, it exposes the /metrics endpoint in a format that Prometheus, one of the most popular monitoring solutions for distributed systems, can scrape.
To watch CronJobs this way you have to watch three objects: CronJobs, Jobs, and Pods. kube-state-metrics publishes the ones you will query most often:
kube_cronjob_infokube_cronjob_status_activekube_cronjob_status_last_schedule_timekube_job_status_failedkube_job_status_succeededkube_pod_info
The next step in this approach would be to prepare custom Prometheus queries that can catch a failure. You’d also need a properly configured Alertmanager (part of Prometheus), which can notify you on Slack or email about errors.
The Cronitor Kubernetes agent skips that query work. It watches CronJob objects and reports successes and failures to Cronitor, which keeps the run history and sends the alert.
Using the Cronitor Kubernetes Agent
Create an account if you do not have one. The Hacker plan is free and includes five monitors, email and chat alerts (Slack, Discord, Microsoft Teams, and webhooks), and one basic status page. Branded and private status pages are paid.
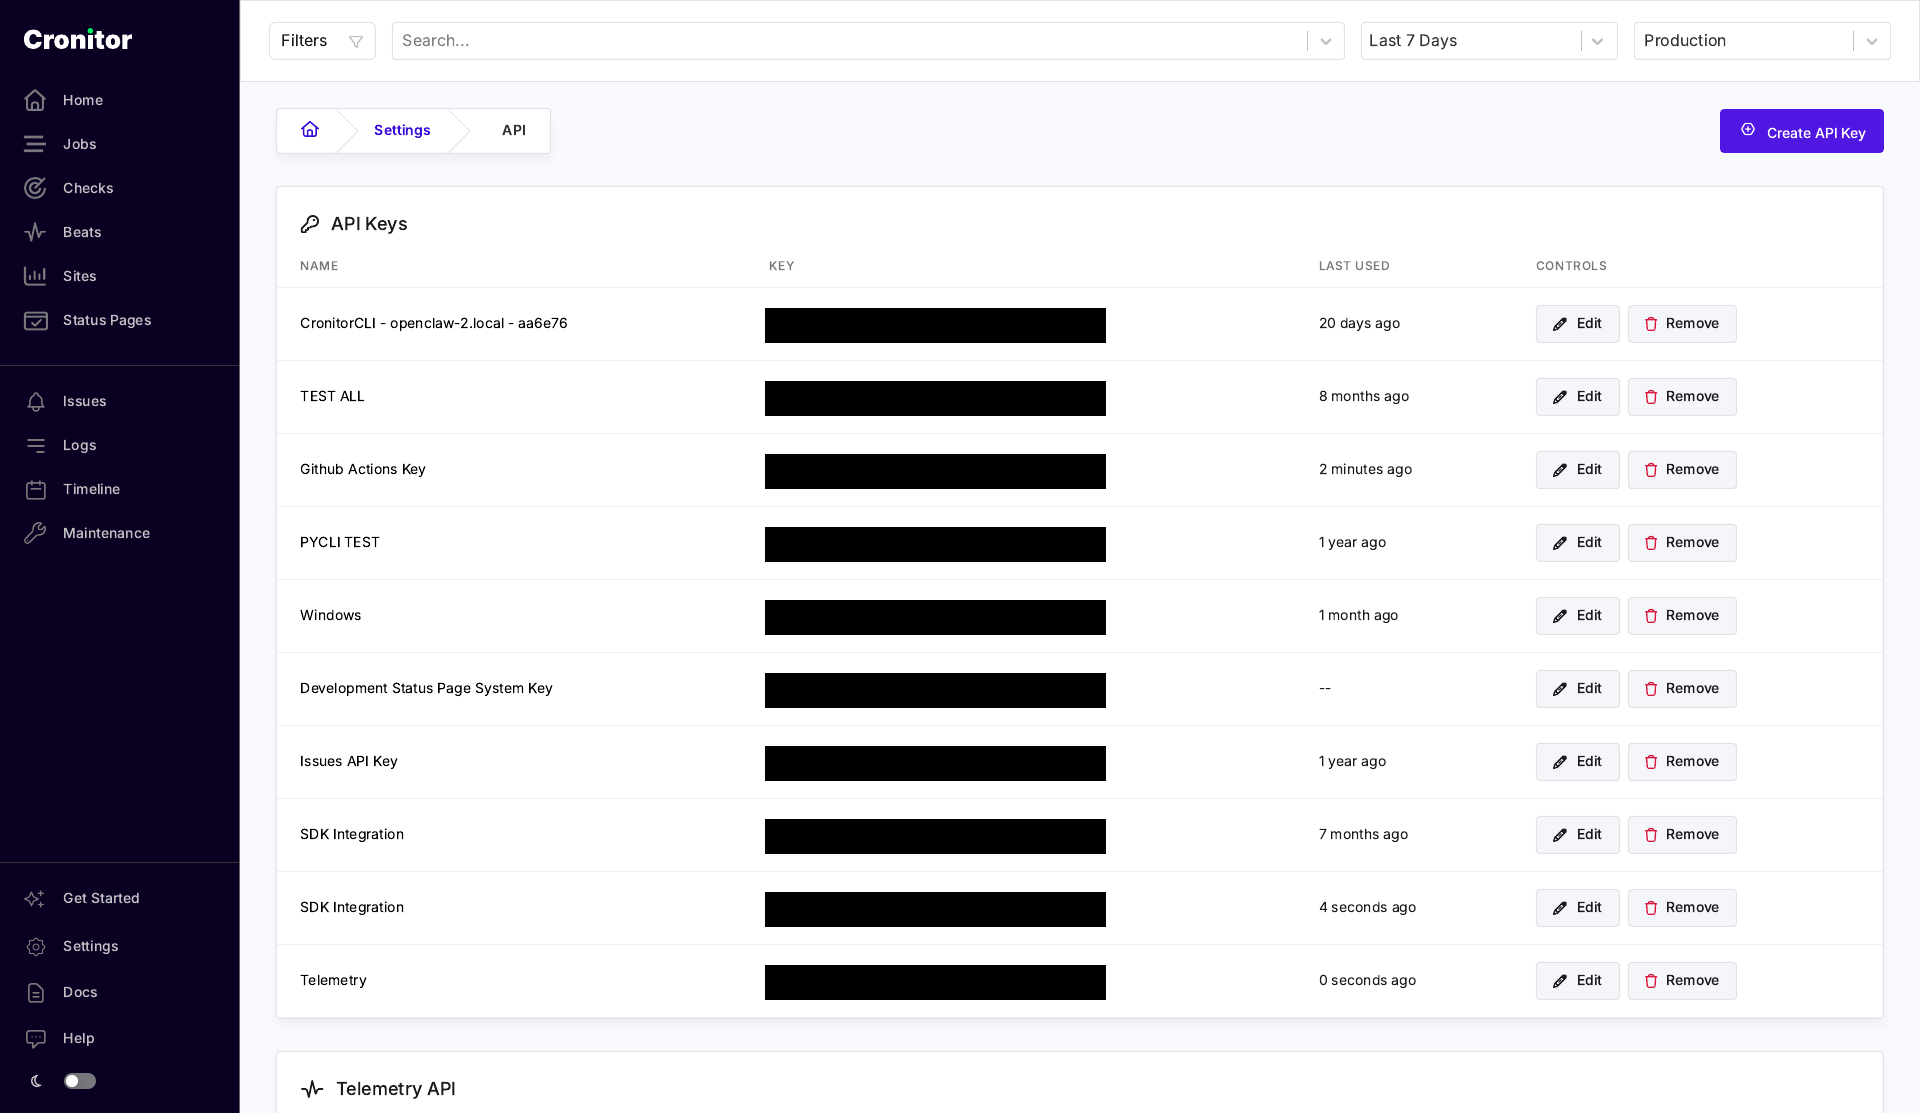
The agent needs an API key that can create monitors. Open Settings at the bottom of the left menu, then the API card. On the API Keys page, copy an SDK Integration key. A Telemetry key can send pings, and it cannot create monitors. The values in the screenshot are covered.
Deploy the agent with Helm. These commands follow the chart's external Secret install. Read Safe agent rollout before you point them at a cluster that already has CronJobs. Replace <namespace> with the namespace the agent should run in, and replace <your-api-key> with the SDK Integration key. Do not commit the command after you paste the real key.
- Add the Helm chart repository:
helm repo add cronitor https://cronitorio.github.io/cronitor-kubernetes/
- Create a Kubernetes Secret in that namespace.
<your-api-key>is a placeholder.
kubectl create secret generic cronitor-secret \
    --namespace <namespace> \
    --from-literal=CRONITOR_API_KEY=<your-api-key>
- Install the chart, pointing it at that Secret:
helm upgrade --install cronitor cronitor/cronitor-kubernetes \
    --namespace <namespace> \
    --set credentials.secretName=cronitor-secret \
    --set credentials.secretKey=CRONITOR_API_KEY
kubectl create secret --from-literal leaves the key in your shell history. Prefer a Secret your cluster's secret manager creates, and pass only secretName and secretKey to Helm. The chart can also create the Secret from credentials.createSecret.apiKey when that value lives in an encrypted values file (for example helm-secrets). Do not pass the key with helm --set on the command line.
Apply a sample CronJob, or one of your own:
kubectl apply -f https://raw.githubusercontent.com/kubernetes/website/main/content/en/examples/application/job/cronjob.yaml
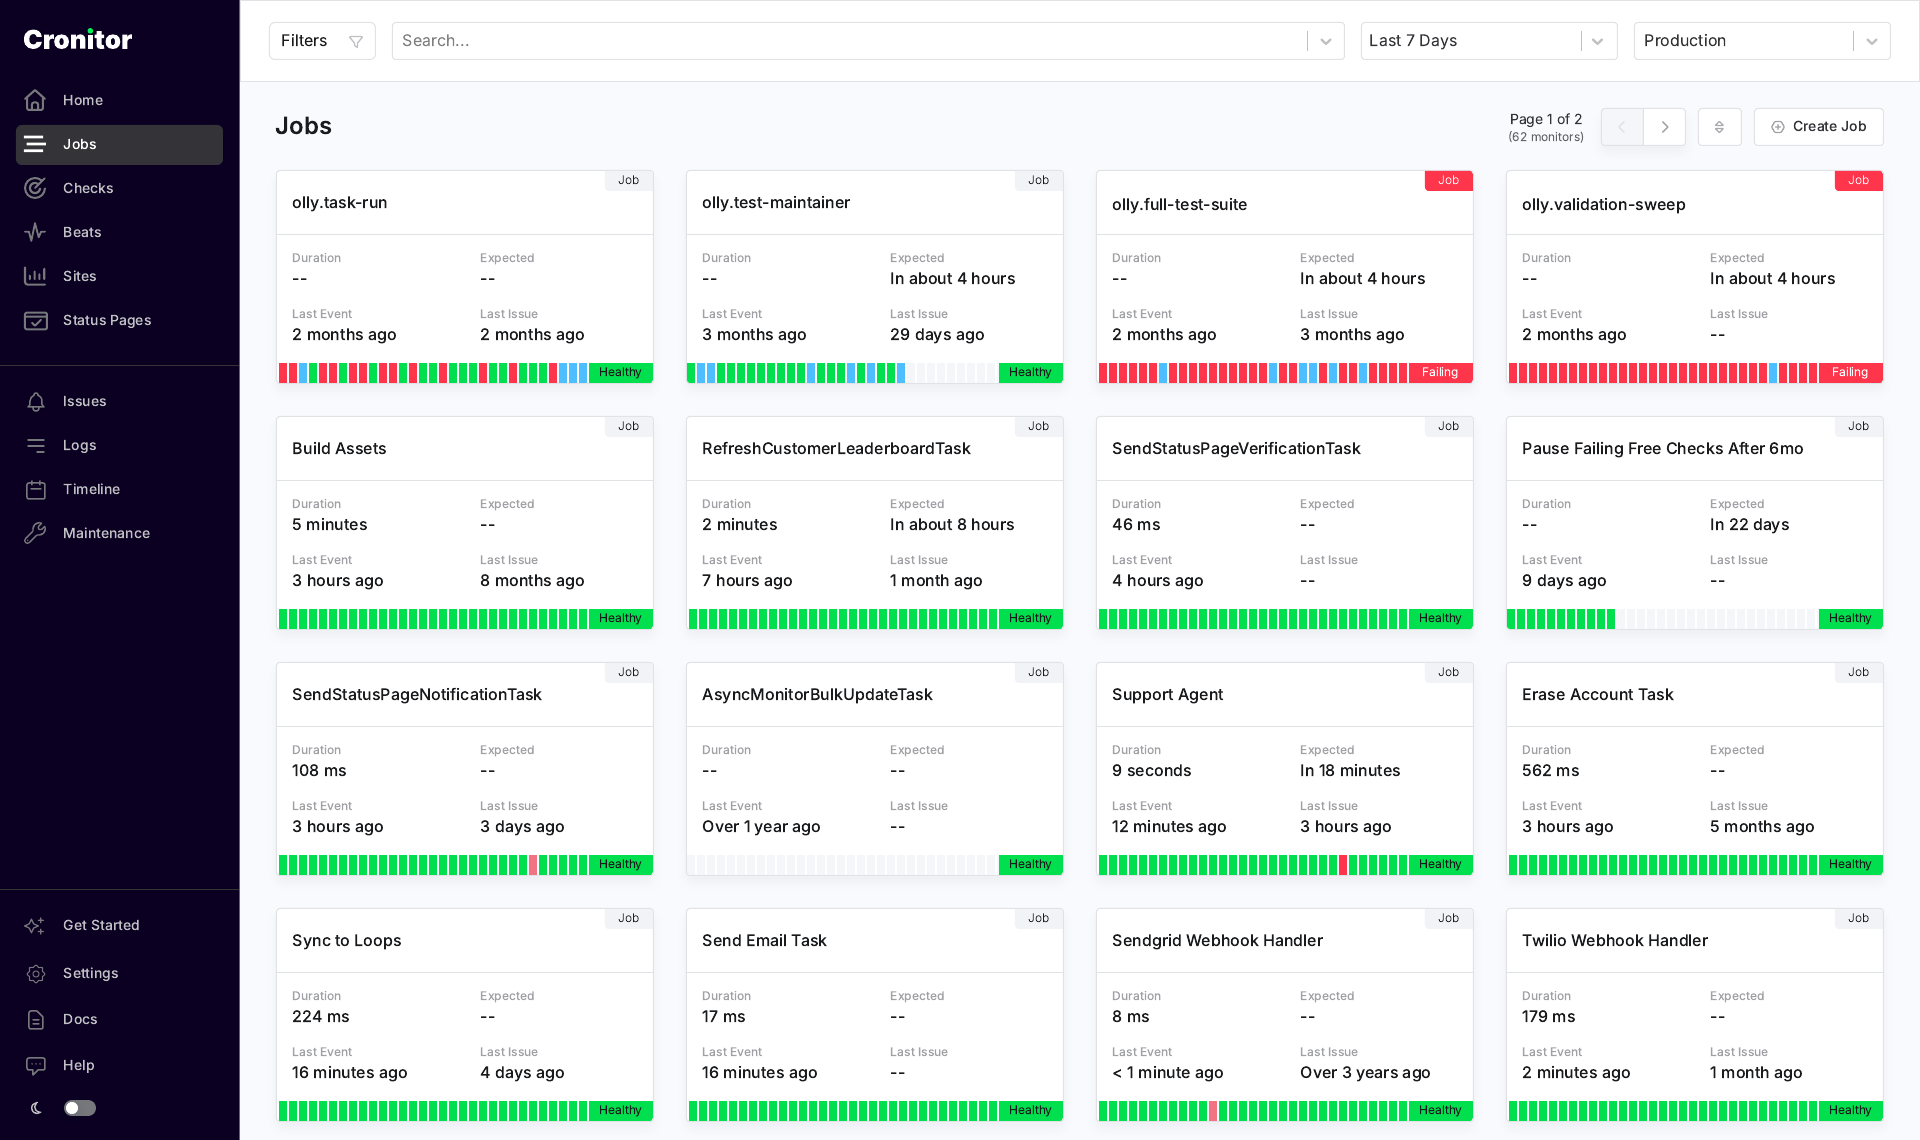
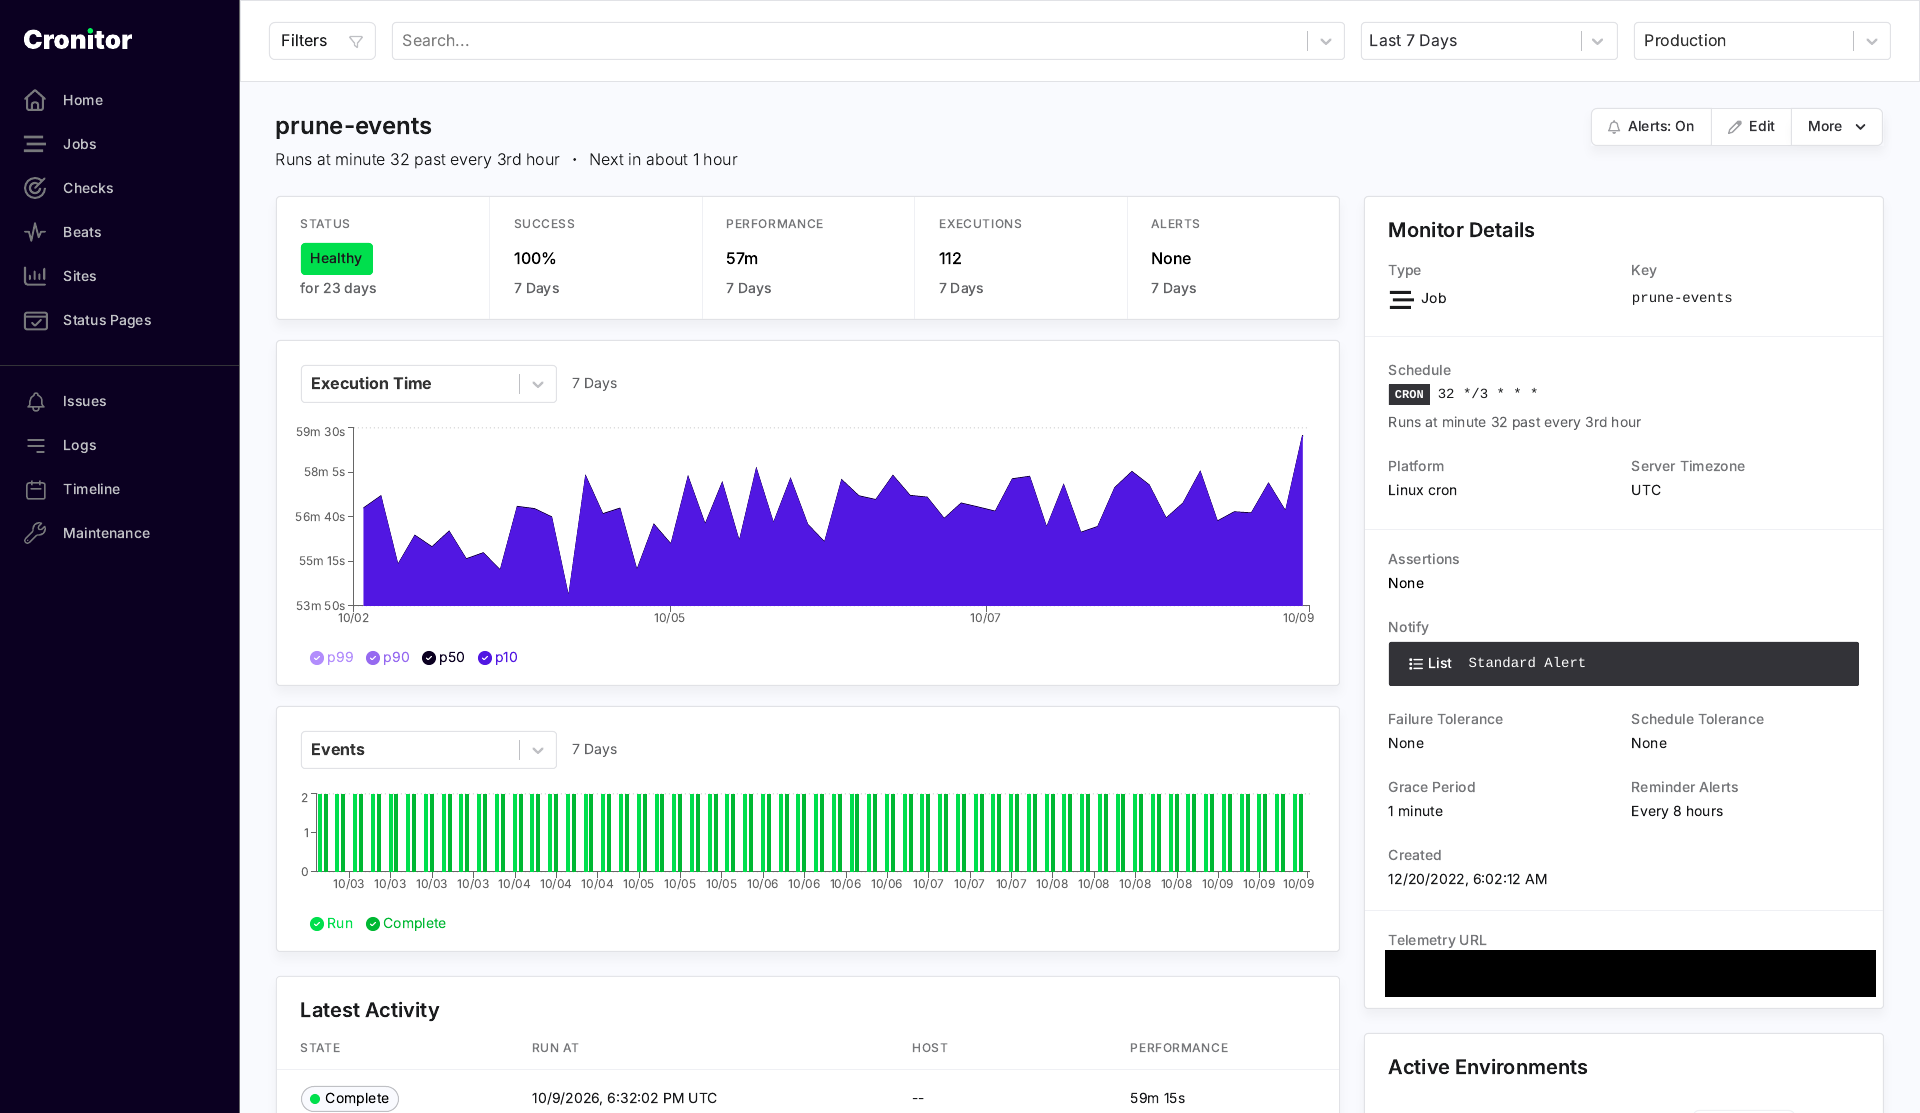
The agent creates the monitor when it sees the CronJob. The Jobs list shows that monitor before the first run. Duration and the latest activity fill in after a run. The screenshots are ordinary job monitors, and the list includes jobs that are not crontab entries. The job in the detail screenshot is a Linux cron job (Platform: Linux cron). A CronJob monitor uses the same pages.
If you only have access to some namespaces, set rbac.clusterScope to namespace and install the chart once in each namespace you want watched. Annotations on the CronJob include or exclude a single job. Both are covered in the FAQ and the annotation reference.
Safe agent rollout
The chart's defaults are broad. config.default is include, so every CronJob in scope is monitored. rbac.clusterScope is cluster, so the agent asks for a ClusterRole. config.sentryEnabled and config.shipLogs are both true, so the agent sends its own errors to Sentry and uploads Pod logs to Cronitor. Change those before the first install if that is wider than you want.
- Set
config.defaulttoexclude, then add the annotationk8s.cronitor.io/include: "true"only on the CronJobs you want monitored. - Set
rbac.clusterScopetonamespaceunless the agent should see the whole cluster. It then uses a Role in its own namespace. Install the chart once per namespace if you need more than one. - Point the chart at a Secret from your secret manager (
credentials.secretNameandcredentials.secretKey). Do not put the API key inhelm --set, in a committed values file, or in a command someone will copy. - Set
config.sentryEnabledandconfig.shipLogstofalseif you do not want agent error reports or job logs sent out of the cluster. - Set the annotation
k8s.cronitor.io/keywhen the monitor should keep the same identity after the CronJob is recreated, or when the same job in more than one cluster should report to one monitor. - Run
helm template(or look at the GitOps diff) and check the namespaces and CronJobs before you apply the release.
The chart contract is the install instructions, the annotations, and values.yaml.
Conclusion
CronJobs fail in a few repeatable ways: a bad manifest, a retry that collides with concurrencyPolicy: Forbid, a Pod that cannot be scheduled, or a tick the controller missed. kube-state-metrics can expose that state to Prometheus. The Cronitor agent reports the same runs without a custom query. Sign up and install the chart if you want the alert when a job does not run.